About the Author
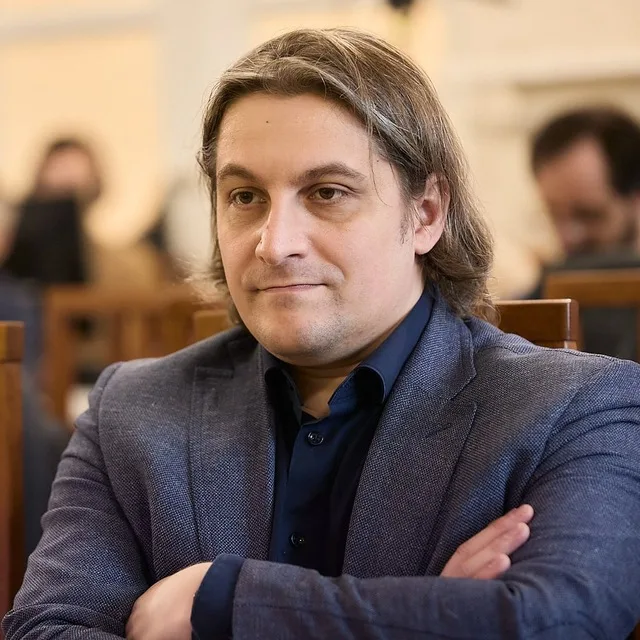
Ivan Begtin works on open data: he collects and analyses government and research data, builds services that help people find it, and writes about how it is published. He is the founder and CTO of the Dateno dataset search engine, the founder and director of the non-profit Infoculture ("Information Culture"), and a co-founder of the Open Data Armenia project (opendata.am).
He has worked on government openness and open data since 2009, and on data catalogs since 2010. This book grew out of the same work. He started the catalog registry from which the book's figures are calculated for his own projects, and many examples and counts in the chapters come from his notes.
Career
Ivan Begtin has worked in IT since 1999. He started out administering Unix servers, then worked as a developer and headed a data mining laboratory.
In 2009 he launched the project "The State and Its Information" (opengovdata.ru), with news and a knowledge base on open government data in Russia. The project ran until 2015. At the same time he began saving copies of government websites that were being closed or changed.
In 2010 he became one of the founders of the Apps4Russia contest, in which developers built applications on government data. In March 2012 the contest's founders set up the non-profit Infoculture, and Ivan Begtin has led it ever since. Infoculture's projects include Goszatraty (clearspending.ru), an open database of government contracts, and the annual Open Data Day in Moscow.
From 2019 to 2021 he headed the Open Data project area at the Accounts Chamber of Russia. There a team of six built the Gosraskhody portal (spending.gov.ru) in four and a half months. It launched in November 2019 with contracts, subsidies and spending on national projects, and the data itself was served as open data and through an API.
Another long-standing interest of the author is plain language in government texts. In 2014 he adapted to Russian the readability formulas that English-speaking countries use to check official texts. This book follows the same rules: simple words and the conclusion first.
Data catalogs
The first catalog was the Hub of Open Data, hubofdata.ru, on CKAN. Ivan Begtin built it in 2010–2011 under the OpenGovData brand, and it appeared before Russia's government open data portals (see the short history of catalogs). Later Infoculture launched a data portal for non-profit organisations, NGO Data (ngodata.ru), on the same platform. The book mentions both community portals in the chapter on metadata export: in November 2024 Google Dataset Search ranked their datasets first for Russian-language queries, because their pages carry schema.org markup for search engines.
Ten years later there were so many catalogs that catalogs of catalogs became necessary. In November 2021 Infoculture launched datacatalogs.ru, a list of Russia's data catalogs, with 245 records at launch. In 2023 the work went beyond one country. The Common Data Index project started an open registry of catalogs from around the world, which had 1.7 thousand records in April 2023. Today this is the dataportals-registry: release 1.27.0 of 15 October 2026 describes 43,614 catalogs and 790 platforms.
In March 2024 the Dateno search engine went live on top of the registry. From a registry record it learns a catalog's platform and API addresses and uses them to collect dataset descriptions. As of 16 October 2026 Dateno holds 22 million datasets from 5,236 sources. Why some catalogs are easy to harvest while the harvester never reaches others is explained in the chapters "Search Engines and Aggregators" and "Discoverability".
Preservation and tools
Since 2017 Infoculture has run the National Digital Archive (ruarxive.org). It saves websites and data that may disappear, above all government ones. In 2022 the archive ran a campaign to archive open data portals, and in 2025 it saved the websites of Rosstat and the EMISS statistics system. How such work is done is described in the chapter "Archiving and Rescuing Catalogs".
For his work the author writes open source tools. undatum processes data files from the command line: CSV, NDJSON, XML and other formats. metacrafter identifies what is in a table's columns: identifiers, codes, personal data. apibackuper saves data that is served only page by page through an API. It is mentioned in the chapters on APIs and bulk download and on archiving.
The author and the book's sources
The book and the data catalog knowledge base are supported by Dateno. The catalog registry and Dateno are the author's projects, so the book cites them more often than others. This can be checked. The registry figures come from open queries, which are collected in the appendix "Using the Registry" and give the same numbers on release 1.27.0. Software versions and platform capabilities were checked against the platforms' own documentation, not against the registry.
The author's notes from his Telegram channel and newsletter are signed "I. Begtin" in the "Sources" sections, and each has a date. They are observations as of the day of the note. If a figure may have changed since, check the date.
Where to read and how to get in touch
- Telegram channel "Ivan Begtin" (in Russian): open data, data engineering, government, privacy and digital preservation. As of 16 October 2026 the channel has 9,093 subscribers.
- Newsletter begtin.substack.com: long texts on the digital, open and preserved state.
- Code: github.com/ivbeg; LinkedIn: linkedin.com/in/ivbeg; ORCID: 0000-0002-9084-9643.
- Email: ivan@begtin.tech.
Comments and corrections to the book can be sent by email or on Telegram.
Sources
- The author's profiles: GitHub: the Dateno, APICrafter, Open Data Armenia and Infoculture projects; LinkedIn: "The State and Its Information" (2009–2015), saving government websites (since 2009), Apps4Russia (since 2010), the National Digital Archive (since 2017); Telegram channel description: the channel's topics and number of subscribers as of 16 October 2026; Facebook: co-founder of Open Data Armenia, the Accounts Chamber in 2019–2021
- TAdviser, Begtin Ivan Viktorovich (in Russian): work in IT since 1999, the data mining laboratory, co-founder of Apps4Russia
- NGO Data, the Infoculture organisation page (in Russian): the organisation was set up in March 2012 by the founders of the Apps4Russia contest
- TAdviser, Gosraskhody (in Russian): launched on 18 November 2019, built from June to November 2019 by six people, open data and API; Roscongress, speaker profile (in Russian): head of the Open Data project area at the Accounts Chamber
- I. Begtin, What "Plain Russian" means from a technology perspective, Habr (in Russian), 2 October 2014: readability formulas for Russian
- I. Begtin, Telegram (in Russian): the Hub of Open Data, built in 2010–2011 under the OpenGovData brand, 14 April 2021; the launch of datacatalogs.ru, 3 November 2021; Common Data Index and the catalog registry, 10 April 2023; the launch of Dateno, 13 March 2024
- The dataportals-registry of data catalogs, release 1.27.0 of 15 October 2026; Dateno as of 16 October 2026
- National Digital Archive; Open Data Armenia